Where extra complexity pays off: five “Just Accepted” papers in ACM TORS
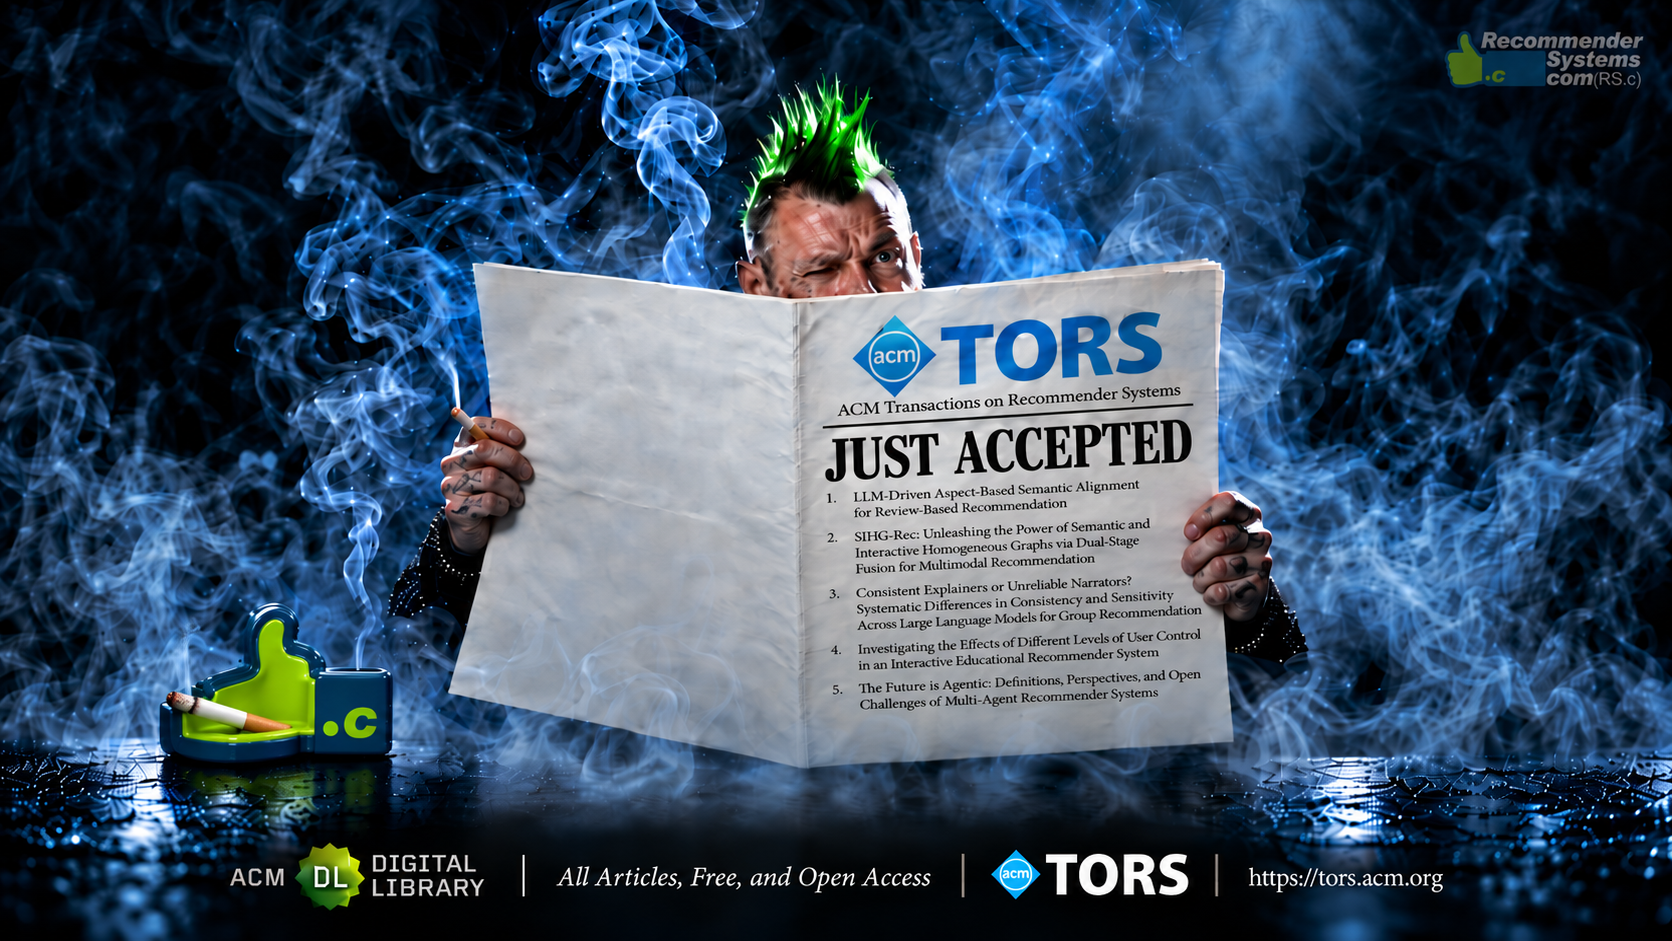
Recommender systems keep gaining components: richer representations, additional graphs, LLM calls, user controls, and multi-agent pipelines. The five latest papers accepted at ACM Transactions on Recommender Systems (TORS) approach this development from different directions: reviews [1], sparse multimodal recommendation [2], group decisions [3], user control [4], and agentic recommendation [5]. Across them, a useful question emerges: which users or inputs actually benefit from the additional machinery?
Messy reviews and thin histories
In LLM-Driven Aspect-Based Semantic Alignment for Review-Based Recommendation, Huilin Chen, Zhiyong Cheng, Richang Hong, and Meng Wang from Hefei University of Technology and Fan Liu from Southeast University examine a mismatch between interaction data and reviews [1]. A purchase may look like positive feedback even when the accompanying review contains dissatisfaction. The paper illustrates this with a customer who buys Dickies trousers but writes that they run one to two sizes too small.
LLM-ASAR uses an LLM to assign review sentences to aspects such as quality, size, or design. These annotations are then used to construct aspect-specific interaction graphs. On the Office, Baby, and Clothing datasets, LLM-ASAR improves NDCG@10 over the strongest baseline by 5.69%, 5.13%, and 7.74%, respectively [1]. The LLM is therefore used to structure the review information before recommendation rather than to generate the recommendations directly.
Jinfeng Xu and Edith Ngai from The University of Hong Kong, Zheyu Chen and Xiping Hu from Beijing Institute of Technology, Wei Wang from Macao Polytechnic University, and Sang-Wook Kim from Hanyang University study a related problem in SIHG-Rec: Unleashing the Power of Semantic and Interactive Homogeneous Graphs via Dual-Stage Fusion for Multimodal Recommendation [2]. SIHG-Rec constructs separate semantic and interaction-based graphs for users and items and combines them through two stages of multimodal fusion.
Its largest improvements occur in the cold-start experiment. For each cold user, only three interactions are retained for training. Across Baby, Sports, and Clothing, SIHG-Rec improves the four reported ranking metrics by 87.3% to 97.4% relative to COHESION, the strongest baseline [2]. On Baby, for example, Recall@10 rises from 0.0145 to 0.0286. The absolute values remain low, but the result shows where the additional graph structure has its strongest effect: users for whom very little interaction evidence is available.
Who is really making the decision?
Consistent Explainers or Unreliable Narrators, by Cedric Waterschoot, Nava Tintarev, and Francesco Barile from Maastricht University, moves from individual recommendation to groups [3]. The authors generate 600 synthetic four-person groups with different preference configurations and item-set sizes. Four LLMs process these groups in three domains, yielding 7,200 recommendations and explanations [3].
The models behave quite differently when their rankings are compared with established social-choice aggregation strategies. Against Additive Utilitarian aggregation, which selects items from the sum of group members’ ratings, average NDCG@10 ranges from 0.63 for Ministral-3 to 0.98 for GPT-OSS 120B [3]. Model choice also affects consistency. At temperature 0.5, GPT-OSS 120B reaches a Jaccard similarity of 0.975 for item overlap and Kendall’s τ of 0.942 for ranking order across repeated runs. Ministral-3 reaches 0.701 and 0.171, respectively [3]. In this setting, selecting an LLM also means selecting a particular, and sometimes unstable, way of reconciling group preferences.
Qurat Ul Ain, Mohamed Amine Chatti, William Kana Tsoplefack, Rawaa Alatrash, and Shoeb Joarder from the Faculty of Computer Science at the University of Duisburg Essen – Campus Duisburg study control from the user’s side [4]. Their paper, Investigating the Effects of Different Levels of User Control in an Interactive Educational Recommender System, compares four versions of the CourseMapper recommender: basic control, control over the user profile, control over the recommendation process, and control over the output.
The between-subjects study includes 184 participants, 46 per condition [4]. Input control produces the highest mean perceived-control score at 3.51, while output control produces the lowest at 2.96. Only the input-versus-output difference is significant in the post-hoc comparison. More generally, perceived control is the only measured outcome that differs significantly across the control conditions; transparency, trust, satisfaction, and perceived recommendation quality do not [4]. Adding more places where users can intervene therefore does not automatically improve all aspects of the user experience. In this experiment, editing the user profile has the clearest effect on perceived control.
When more agents are worth the cost
The Future is Agentic: Definitions, Perspectives, and Open Challenges of Multi-Agent Recommender Systems, by Reza Yousefi Maragheh from the University of Illinois Urbana Champaign and Yashar Deldjoo from Polytechnic University of Bari, develops a framework for agentic recommender systems and tests several such designs empirically [5].
The experiment compares seven LLM workflows on Amazon-2023 data, from a single LLM call to combinations of planners, profilers, multiple rankers, critics, and arbitrators. The authors evaluate 400 randomly sampled users and another 400 users selected for highly diverse histories [5].
For the random sample, more agents barely help. The single-shot pipeline reaches NDCG@10=0.7197; the best multi-agent result is 0.7209 [5]. The picture changes for diverse histories. A pipeline with a planner, profiler, three rankers, and an arbitrator raises NDCG@3 from 0.4898 to 0.5202, a 6.2% relative improvement. A planner with three rankers and an arbitrator obtains the best NDCG@10, increasing it from 0.6316 to 0.6471 [5].
The paper also reports the price of this improvement. On the high-diversity sample, a single call uses about 1,654 tokens and costs $0.00219 per query. The five- and six-call ensemble pipelines use 8,921 and 10,812 tokens and cost $0.01119 and $0.01225, respectively [5]. The additional agents therefore make most sense for the users whose histories are difficult enough to benefit from decomposition and ensembling.
A useful test for additional complexity
The five papers examine very different recommender systems, but their strongest experiments have something in common. They do not rely only on an average result. Chen et al. examine aspect-level review information [1]. Xu et al. create a severe cold-start condition [2]. Waterschoot et al. repeat inference and compare different LLM families [3]. Ul Ain et al. manipulate the point at which users can control the recommender [4]. Maragheh and Deldjoo separate ordinary from high-diversity histories and report cost alongside ranking quality [5].
This suggests a useful test for new recommender-system components: identify the users or inputs for which the component should solve a specific problem, and evaluate those cases separately. An additional graph, LLM call, control mechanism, or agent is much easier to assess when the evaluation shows where it changes the result and where it does not.
Bibliography
[1] Huilin Chen, Zhiyong Cheng, Fan Liu, Richang Hong, and Meng Wang. 2026. LLM-Driven Aspect-Based Semantic Alignment for Review-Based Recommendation. ACM Transactions on Recommender Systems. https://doi.org/10.1145/3843223.
[2] Jinfeng Xu, Zheyu Chen, Wei Wang, Xiping Hu, Sang-Wook Kim, and Edith Ngai. 2026. SIHG-Rec: Unleashing the Power of Semantic and Interactive Homogeneous Graphs via Dual-Stage Fusion for Multimodal Recommendation. ACM Transactions on Recommender Systems. https://doi.org/10.1145/3847662.
[3] Cedric Waterschoot, Nava Tintarev, and Francesco Barile. 2026. Consistent Explainers or Unreliable Narrators: Systematic Differences in Consistency and Sensitivity Across Large Language Models for Group Recommendations. ACM Transactions on Recommender Systems. https://doi.org/10.1145/3848640.
[4] Qurat Ul Ain, Mohamed Amine Chatti, William Kana Tsoplefack, Rawaa Alatrash, and Shoeb Joarder. 2026. Investigating the Effects of Different Levels of User Control in an Interactive Educational Recommender System. ACM Transactions on Recommender Systems. https://doi.org/10.1145/3848619.
[5] Reza Yousefi Maragheh and Yashar Deldjoo. 2026. The Future is Agentic: Definitions, Perspectives, and Open Challenges of Multi-Agent Recommender Systems. ACM Transactions on Recommender Systems. https://doi.org/10.1145/3845988.
ACM TORS August/September ’25 Roundup

New in ACM TORS: Smarter Promotions, Fairer Algorithms, and the Upside of Bias
Music Recommender Systems: Call for Papers by ACM TORS for a Special Issue
About The Author

Joeran Beel
I am the founder of Recommender-Systems.com and head of the Intelligent Systems Group (ISG) at the University of Siegen, Germany https://isg.beel.org. We conduct research in recommender-systems (RecSys), personalization and information retrieval (IR) as well as on automated machine learning (AutoML), meta-learning and algorithm selection. Domains we are particularly interested in include smart places, eHealth, manufacturing (industry 4.0), mobility, visual computing, and digital libraries. We founded or maintain, among others, LensKit-Auto, Darwin & Goliath, Mr. DLib, and Docear, each with thousand of users; we contributed to TensorFlow, JabRef and others; and we developed the first prototypes of automated recommender systems (AutoSurprise and Auto-CaseRec) and Federated Meta Learning (FMLearn Server and Client).